Python Package: CrossDA
Milestone:
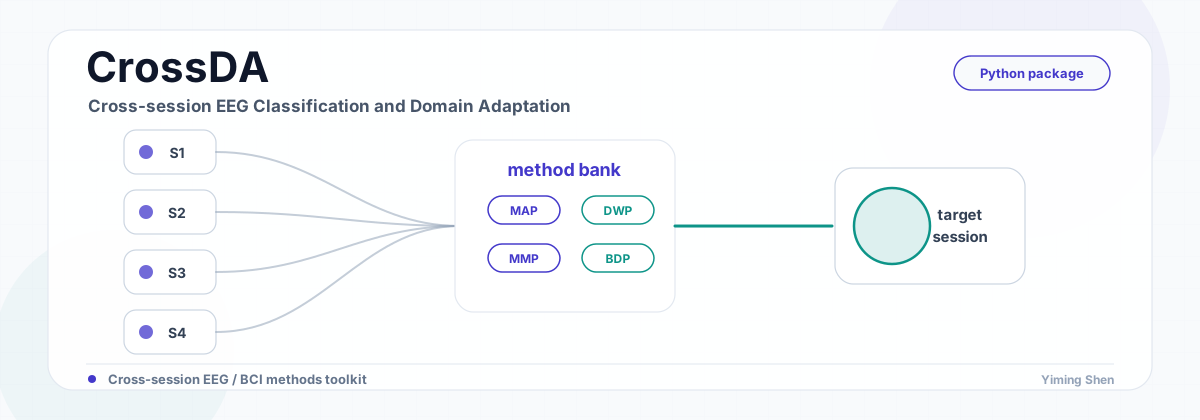
Package: CrossDA
Title: Cross-session EEG Classification and Domain Adaptation Pipelines
Language: Python
Authors: Yiming Shen and David Degras
License: MIT
Overview
CrossDA addresses a comparison problem: pooling all historical data, weighting it, and selecting subsets must be evaluated under comparable model searches. I built a CLI and Python API to run these experiments reproducibly and record the configuration and role of each session. Its empirical setting is transfer across EEG recording sessions of the same participant under leave-one-session-out protocols.
Toolkit Role
CrossDA sits between the method libraries and the dashboards. It executes the pipeline families and writes summary, detail, and session-role outputs that can be inspected downstream.
Feature and DA method banks -> CrossDA -> result files -> MSDA-Bench / custom analysis
Pipeline Families
MAP: Merge and Adapt, using all source sessions after supervised method selection.DWP: Distance-Weighted Pooling, using soft inverse-distance source weights.MMP: Minimum-distance Multi-source, using CI-gated source selection with merge-then-adapt or mixture-of-experts combiners.BDP: Bridge-Domain Proxy, separating bridge and far sessions for proxy-tuned adaptation.
Main Capabilities
- CLI and Python API for reproducible runs.
- Method banks over feature families, classifiers, DA methods, and distance metrics.
- Dataset support for BNCI2014-004, Stieger2021, and Ma2020 workflows.
- Per-subject summaries, detailed run records, and role CSVs documenting train, bridge, far, and target session assignments.
Evaluation and outcome
The package supports the matched source-selection experiments reported in my first-author Frontiers article. On Stieger2021, confidence-gated selection kept selected-configuration performance in the full-pooling and distance-weighted range while using 37% of full pooling’s complete benchmark-search runtime. This is an experimental-search efficiency result, not an inference-latency or production-cost claim. The paper and this software describe the same research contribution, not independent replications.